#Get Started
If you prefer a visual interface or want to deploy standard HTTP functions without setting up a local agent environment, use the Buildfunctions Dashboard.
#Sign Up / Login
Head to https://www.buildfunctions.com/dashboard and sign in with GitHub or your email.
#Create & Deploy
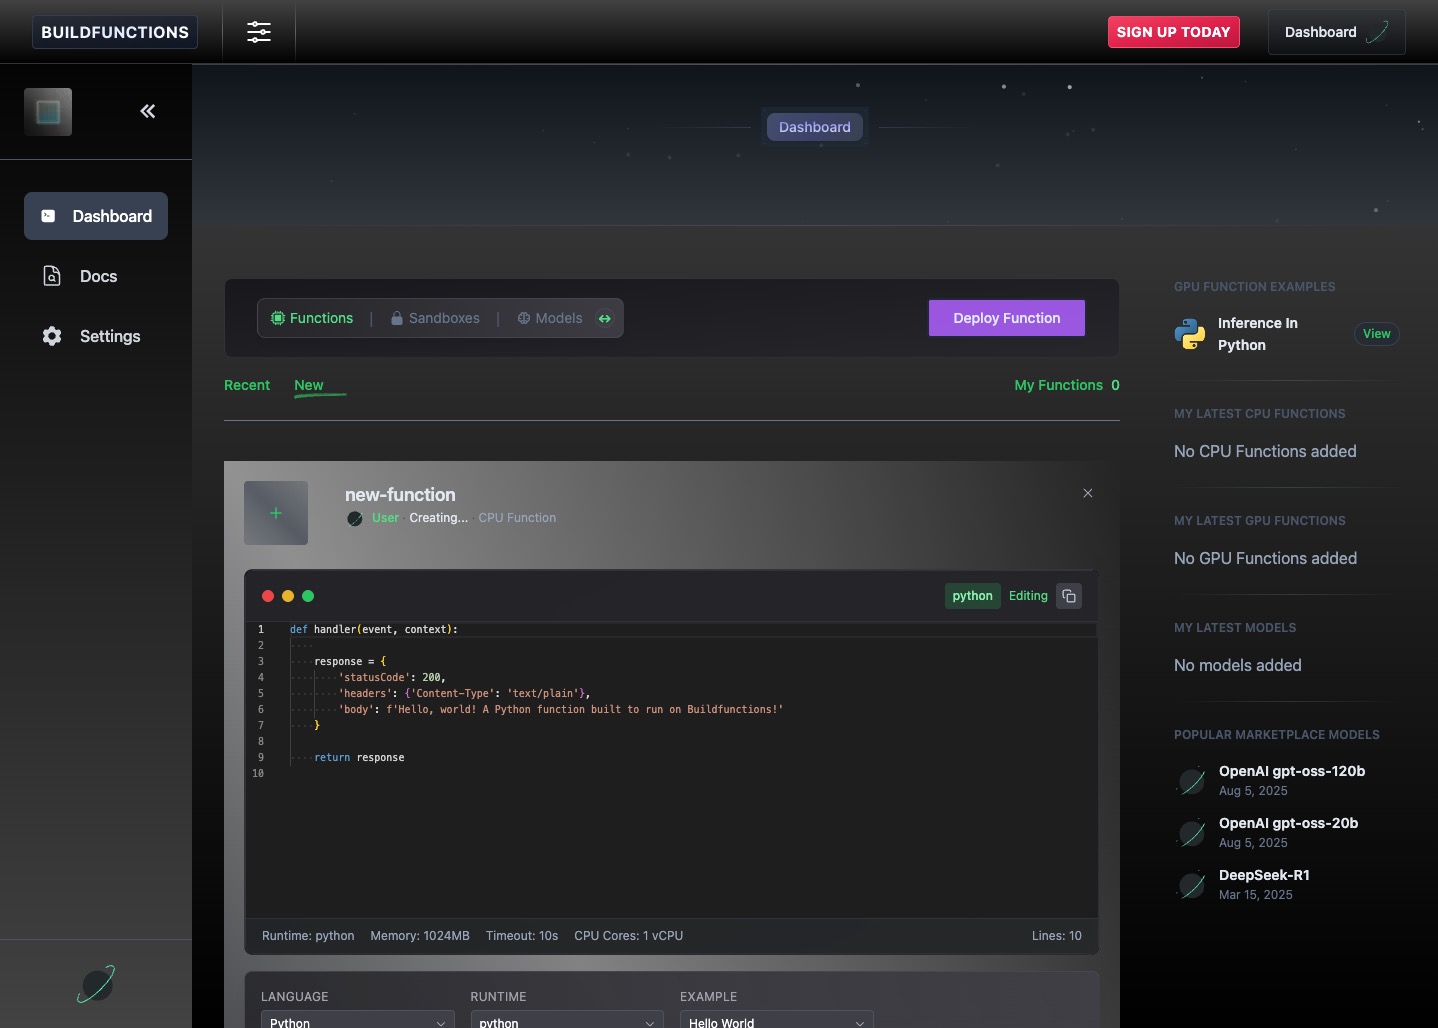
Navigate to the Functions section and click the New tab.
Simply click Deploy Function to immediately deploy a standard "Hello World" handler. You can also write your own code directly in the browser editor and deploy it.
#Advanced: GPU Functions
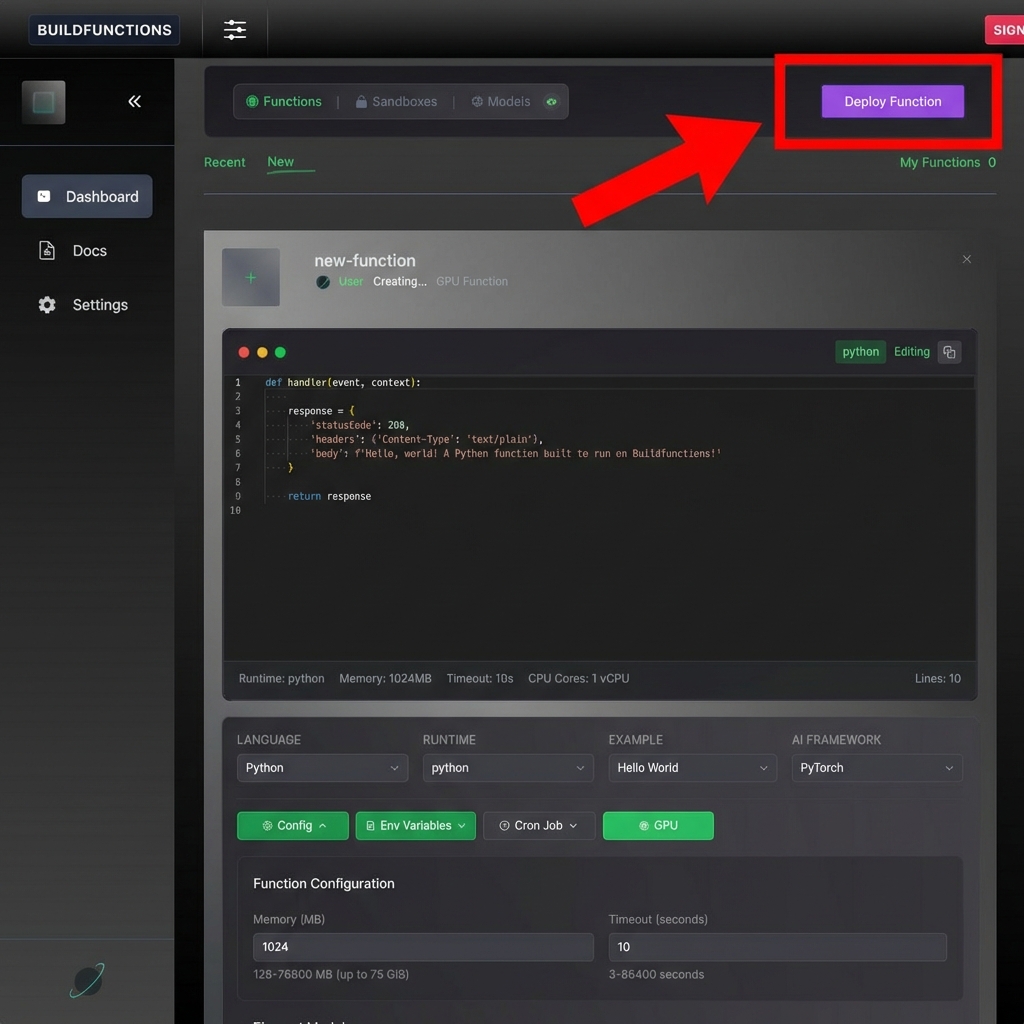
To deploy a GPU function, select the GPU option when creating a function and use one of these templates:
#1. Basic GPU Function
Verifies GPU access and returns device stats.
import sys
import json
import torch

def handler():
    try:
        cuda_available = torch.cuda.is_available()
        device_count = torch.cuda.device_count() if cuda_available else 0
        device_name = torch.cuda.get_device_name(0) if cuda_available and device_count > 0 else "No GPU"
        print(f"Device set to: {device_name}")

        return {
            "statusCode": 200,
            "headers": { "Content-Type": "application/json" },
            "body": json.dumps({
                "message": "Hello from a Buildfunctions GPU Function!",
                "cuda_available": cuda_available,
                "device_name": device_name
            })
        }
    except Exception as e:
        print(f"Error: {e}", file=sys.stderr)
        return { "statusCode": 500, "body": json.dumps({"error": str(e)}) }
#2. Streaming Response
Simulates real-time AI generation.
import sys
import json
import time
import torch

MOCK_RESPONSE = "The most mysterious phenomenon in the universe is dark energy..."

async def stream_mock_response():
    try:
        yield b"<<START_STREAM>>\n"
        for i, word in enumerate(MOCK_RESPONSE.split()):
            token = f" {word}" if i > 0 else word
            yield f"<<STREAM_CHUNK>>{token}<<END_STREAM_CHUNK>>\n".encode()
            time.sleep(0.05)
        yield b"<<END_STREAM>>\n"
    except Exception as e:
        yield b"<<STREAM_ERROR>>\n"

async def async_stream_wrapper():
    async for chunk in stream_mock_response():
        yield chunk

def handler():
    try:
        cuda_available = torch.cuda.is_available()
        device_name = torch.cuda.get_device_name(0) if cuda_available else "No GPU"
        return {
            "statusCode": 200,
            "headers": {
                "Content-Type": "text/event-stream",
                "Cache-Control": "no-cache",
                "X-Device-Name": device_name
            },
            "body": async_stream_wrapper(),
        }
    except Exception as e:
        return {"statusCode": 500, "body": {"error": "Internal Server Error"}}
#Test Your Endpoint
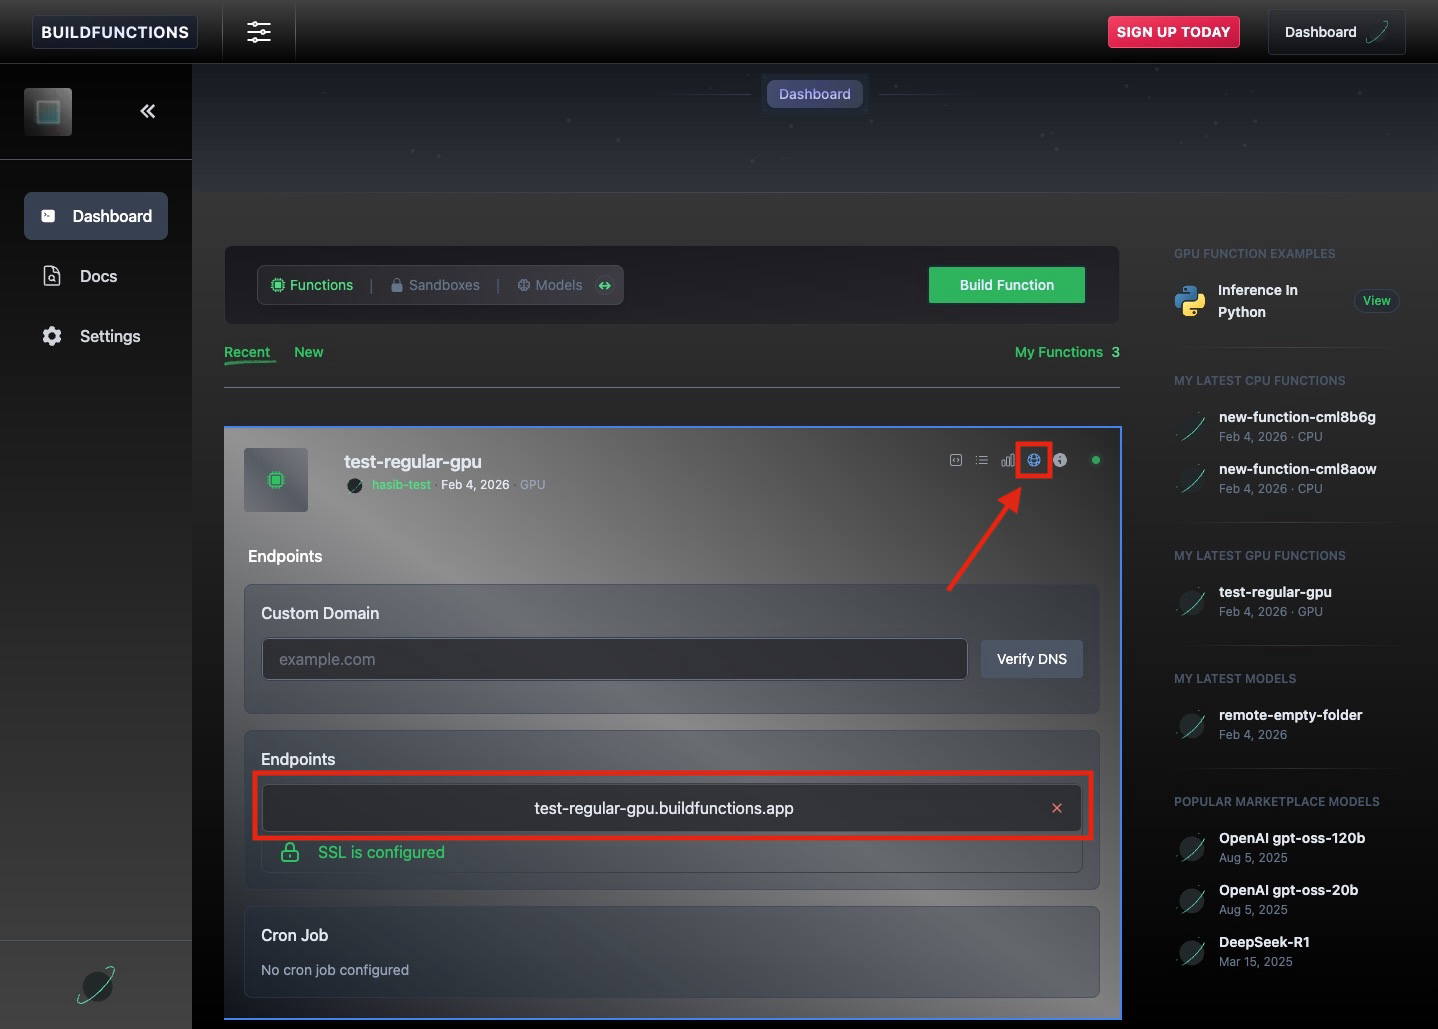
Once deployed, click on your function and navigate to the Network tab.
Here you will see your active Test Endpoints. You can hit this endpoint with any HTTP client to trigger the function.